Overview
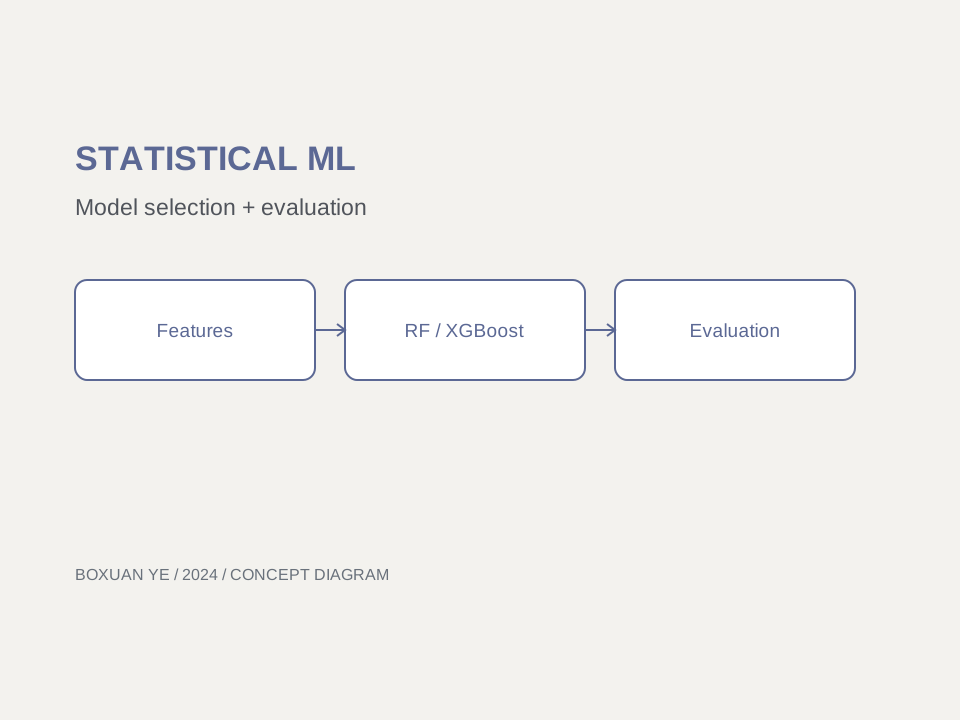
This academic project studies classification using statistical machine-learning methods and examines the contribution of feature selection and model tuning.
Approach
I used Random Forest and XGBoost with GridSearchCV for tuning, recursive feature elimination for feature selection, and UMAP to inspect class separability.
Results & Current Status
The project achieved 81.7% test accuracy for GDP classification on its evaluation split. This result is specific to the project dataset and split.